Transformer
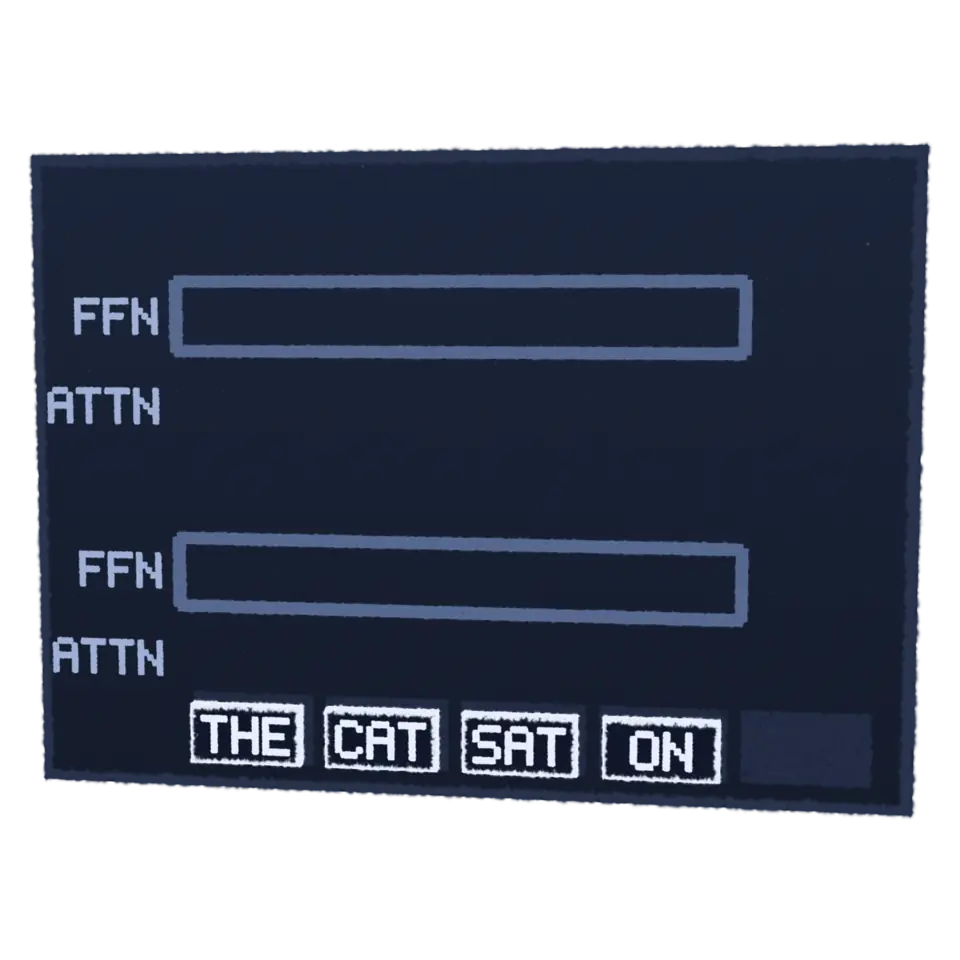
A transformer is a neural network first described in 2017, for translating text.
This picture is a cloud of paint. You can , , , , , , and .
Paint with your finger. It stays on these splats, wherever they go next.
Your paint is on this cloud. to see the sharp picture.
- Shelf
- AI and Computing
- Kind
- Built from a recipe
- Made from
- Encoder–decoder key: ◉ attention · ◒ masked attention · + add & norm · » feed forward · ⠿ embedding · ∿ positional encoding · ╱ linear · ▁▃▇ softmax · N× repeated N times. HELLO WORLD goes in, and the prepared decoder example, given START HOLA, ends with MUNDO. Its words and attention strengths are stored.
- Sound
- Yes
- Licenses
- Own work (made in the page)
How to play
Tap it to watch a prepared next-word example. Try the Encoder–decoder diagram in the Splash tab.
Its controls
| Control | Kind | Range | Start |
|---|---|---|---|
| Predict the next word | Tap | ||
| Predict | Button | ||
| Diagram | List | 2 choices | Token flow |
| View | List | 2 choices | Poster (2D) |
About it
A transformer is a neural network first described in 2017, for translating text. It splits text into tokens, and in each layer every token uses attention: it looks at all the others and weighs how much each one matters to it. Language models built this way predict the next token.
Tap it: arcs jump between THE CAT SAT ON, thicker where attention is stronger, one color for each of two heads; the tiles rise through the layers, and MAT drops in. The Encoder–decoder diagram in the Splash tab is the classic design. Its key: an eye is attention; a lidded eye, masked attention (it only looks back); +, add and norm; », feed forward; a vector, embedding; a wave, positional encoding; a slash, linear; bars, softmax; N×, repeated N times. HELLO WORLD goes in, and given START HOLA, the prepared example ends with MUNDO. The words and attention strengths are prepared; this view does not calculate attention or predict text.
Details
- Splats
- Opens at 200,000 at Mid Detail, 120,002 at Low, and up to 720,000 at Max
Is it right?
The classic encoder-decoder diagram names the main parts of the 2017 transformer correctly. The words and attention arcs are prepared examples; no attention matrix, translation, or next-word inference is calculated.
Correct
The classic diagram follows the 2017 encoder-decoder architecture.1
The box labels include embedding, position, masked self-attention, encoder attention, add and norm, feed-forward, linear, and softmax.
Simplified
The splash presents prepared next-word and translation examples.1
MAT and the MUNDO tile label are literal outputs, and arc strengths are stored. The How-to and About now say that these are prepared examples.
Simplified
The first attention picture is schematic rather than a causal decoder calculation.1
Some arcs lead to later token positions; there is no QK product, mask, normalization, or learned attention value.
- Attention Is All You Need, Vaswani and coauthors, 2017
- Simplified
- MAT and MUNDO are stored outputs. Arc strengths are fixed, not attention probabilities. The first picture permits links to later tokens, so it should not be read as causal decoder attention.
Sources and credits
Made in Splashery. Its code is MIT.
Share it
This link opens it in the Playground. To put it on your own page, add the element and one script tag. Every option.
https://splashery.app/play/?toy=transformer
<script type="module" src="https://splashery.app/play/src/element.js"></script>
<splashery-toy toy="transformer"></splashery-toy>
Nearby
 Neural NetworkA neural network is made of simple artificial neurons in layers.
 PerceptronA perceptron is the simplest artificial neuron, described by Frank Rosenblatt in 1958.
 Recurrent NetworkA recurrent network, or RNN, reads a sequence, like the words of a sentence, one piece at a time.
 Looped TransformerA looped transformer runs the same transformer block again and again, feeding its output back in as its next input, instead of stacking many different layers.